Data pipelines and automationPersonal project
Sift
Job-discovery pipeline: 12 public sources in, deduped and scored for fit and eligibility, a ranked feed out every morning.
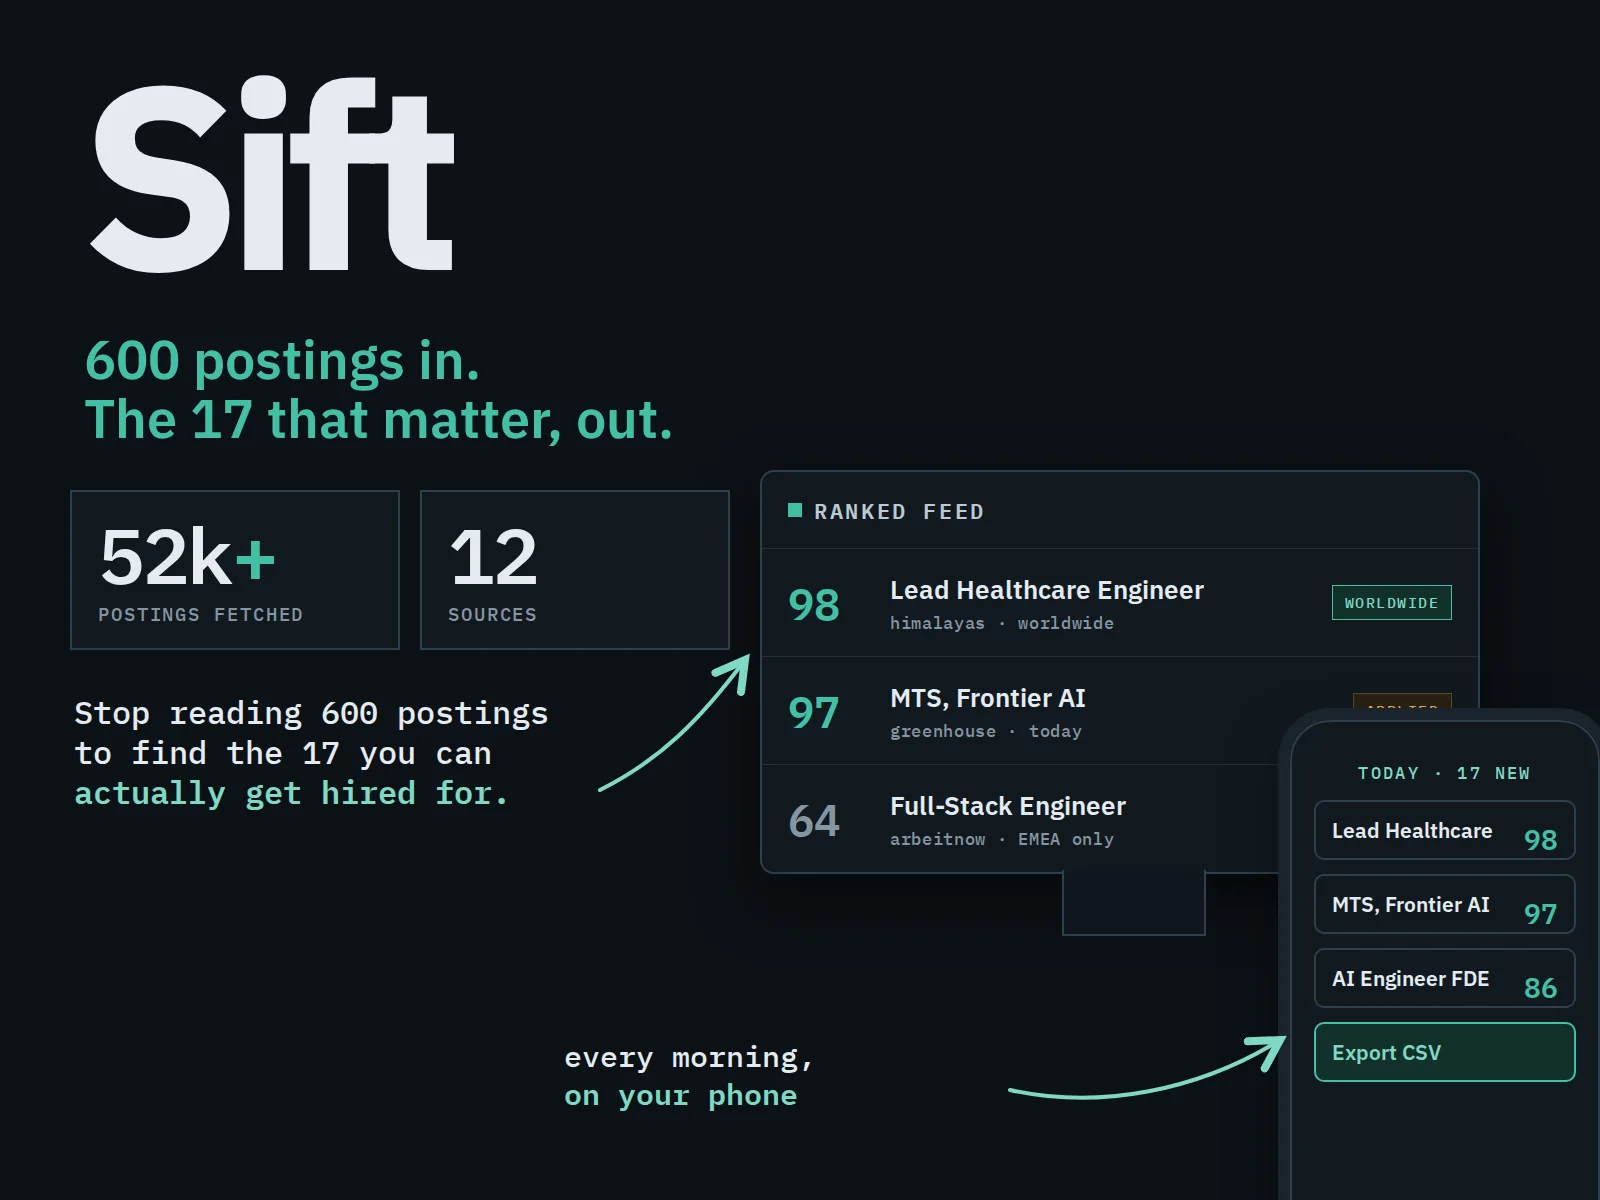
Problem
Finding jobs was never the bottleneck; finding the ones that can actually hire you is. Most "remote" postings are region-locked, so a feed that only matches on role wastes the morning on roles you are not eligible for.
What I built
- Collects from 12 sources, including Greenhouse, Lever, Ashby and Workable ATS APIs per company, plus Himalayas, We Work Remotely RSS, Jobicy, Arbeitnow, Remotive, RemoteOK and Hacker News Who is hiring. Every source runs in isolation, so one broken board never kills the run.
- Normalises everything to one schema (title, company, location, salary, employment type, posted date) and dedupes with a SHA-1 fingerprint: 52k postings fetched became 5,518 unique jobs, with first-seen and last-seen history.
- Scores each posting on 7 weighted signals (role fit, eligibility, niche, freshness, seniority, contractor-friendly, salary and stack). Eligibility weighs as much as fit because only 4.6% of the "remote" postings hire worldwide. Every score explains itself.
- Exports to SQLite, JSON, XLSX and an HTML dashboard with a status dropdown, notes and CSV export. Runs unattended on GitHub Actions every morning; each run logs fetched, kept, new and error counts per source.
- The same collect, normalise, dedupe and score engine runs over a company list for lead enrichment: domain, firmographics, tech and hiring signals, a fit score, CSV or Sheets out. Company-level public data only, rate-limited, robots.txt respected.
- pytest covers the scoring model; a config file tunes minimum score, maximum age, stack keywords and niche weights.
Stack
PythonRequestsPlaywrightSQLiteGitHub ActionspytestREST APIsRSSExcel